 Hyperdrift
We built First Officer so we could ask about the fleet, make a decision and hear the result while the evidence stayed on screen. In the 29 September recording, “bring it back” starts recovery of Cargo, our sandbox service. The officer reports after two consecutive successful external checks.
Thirteen seconds
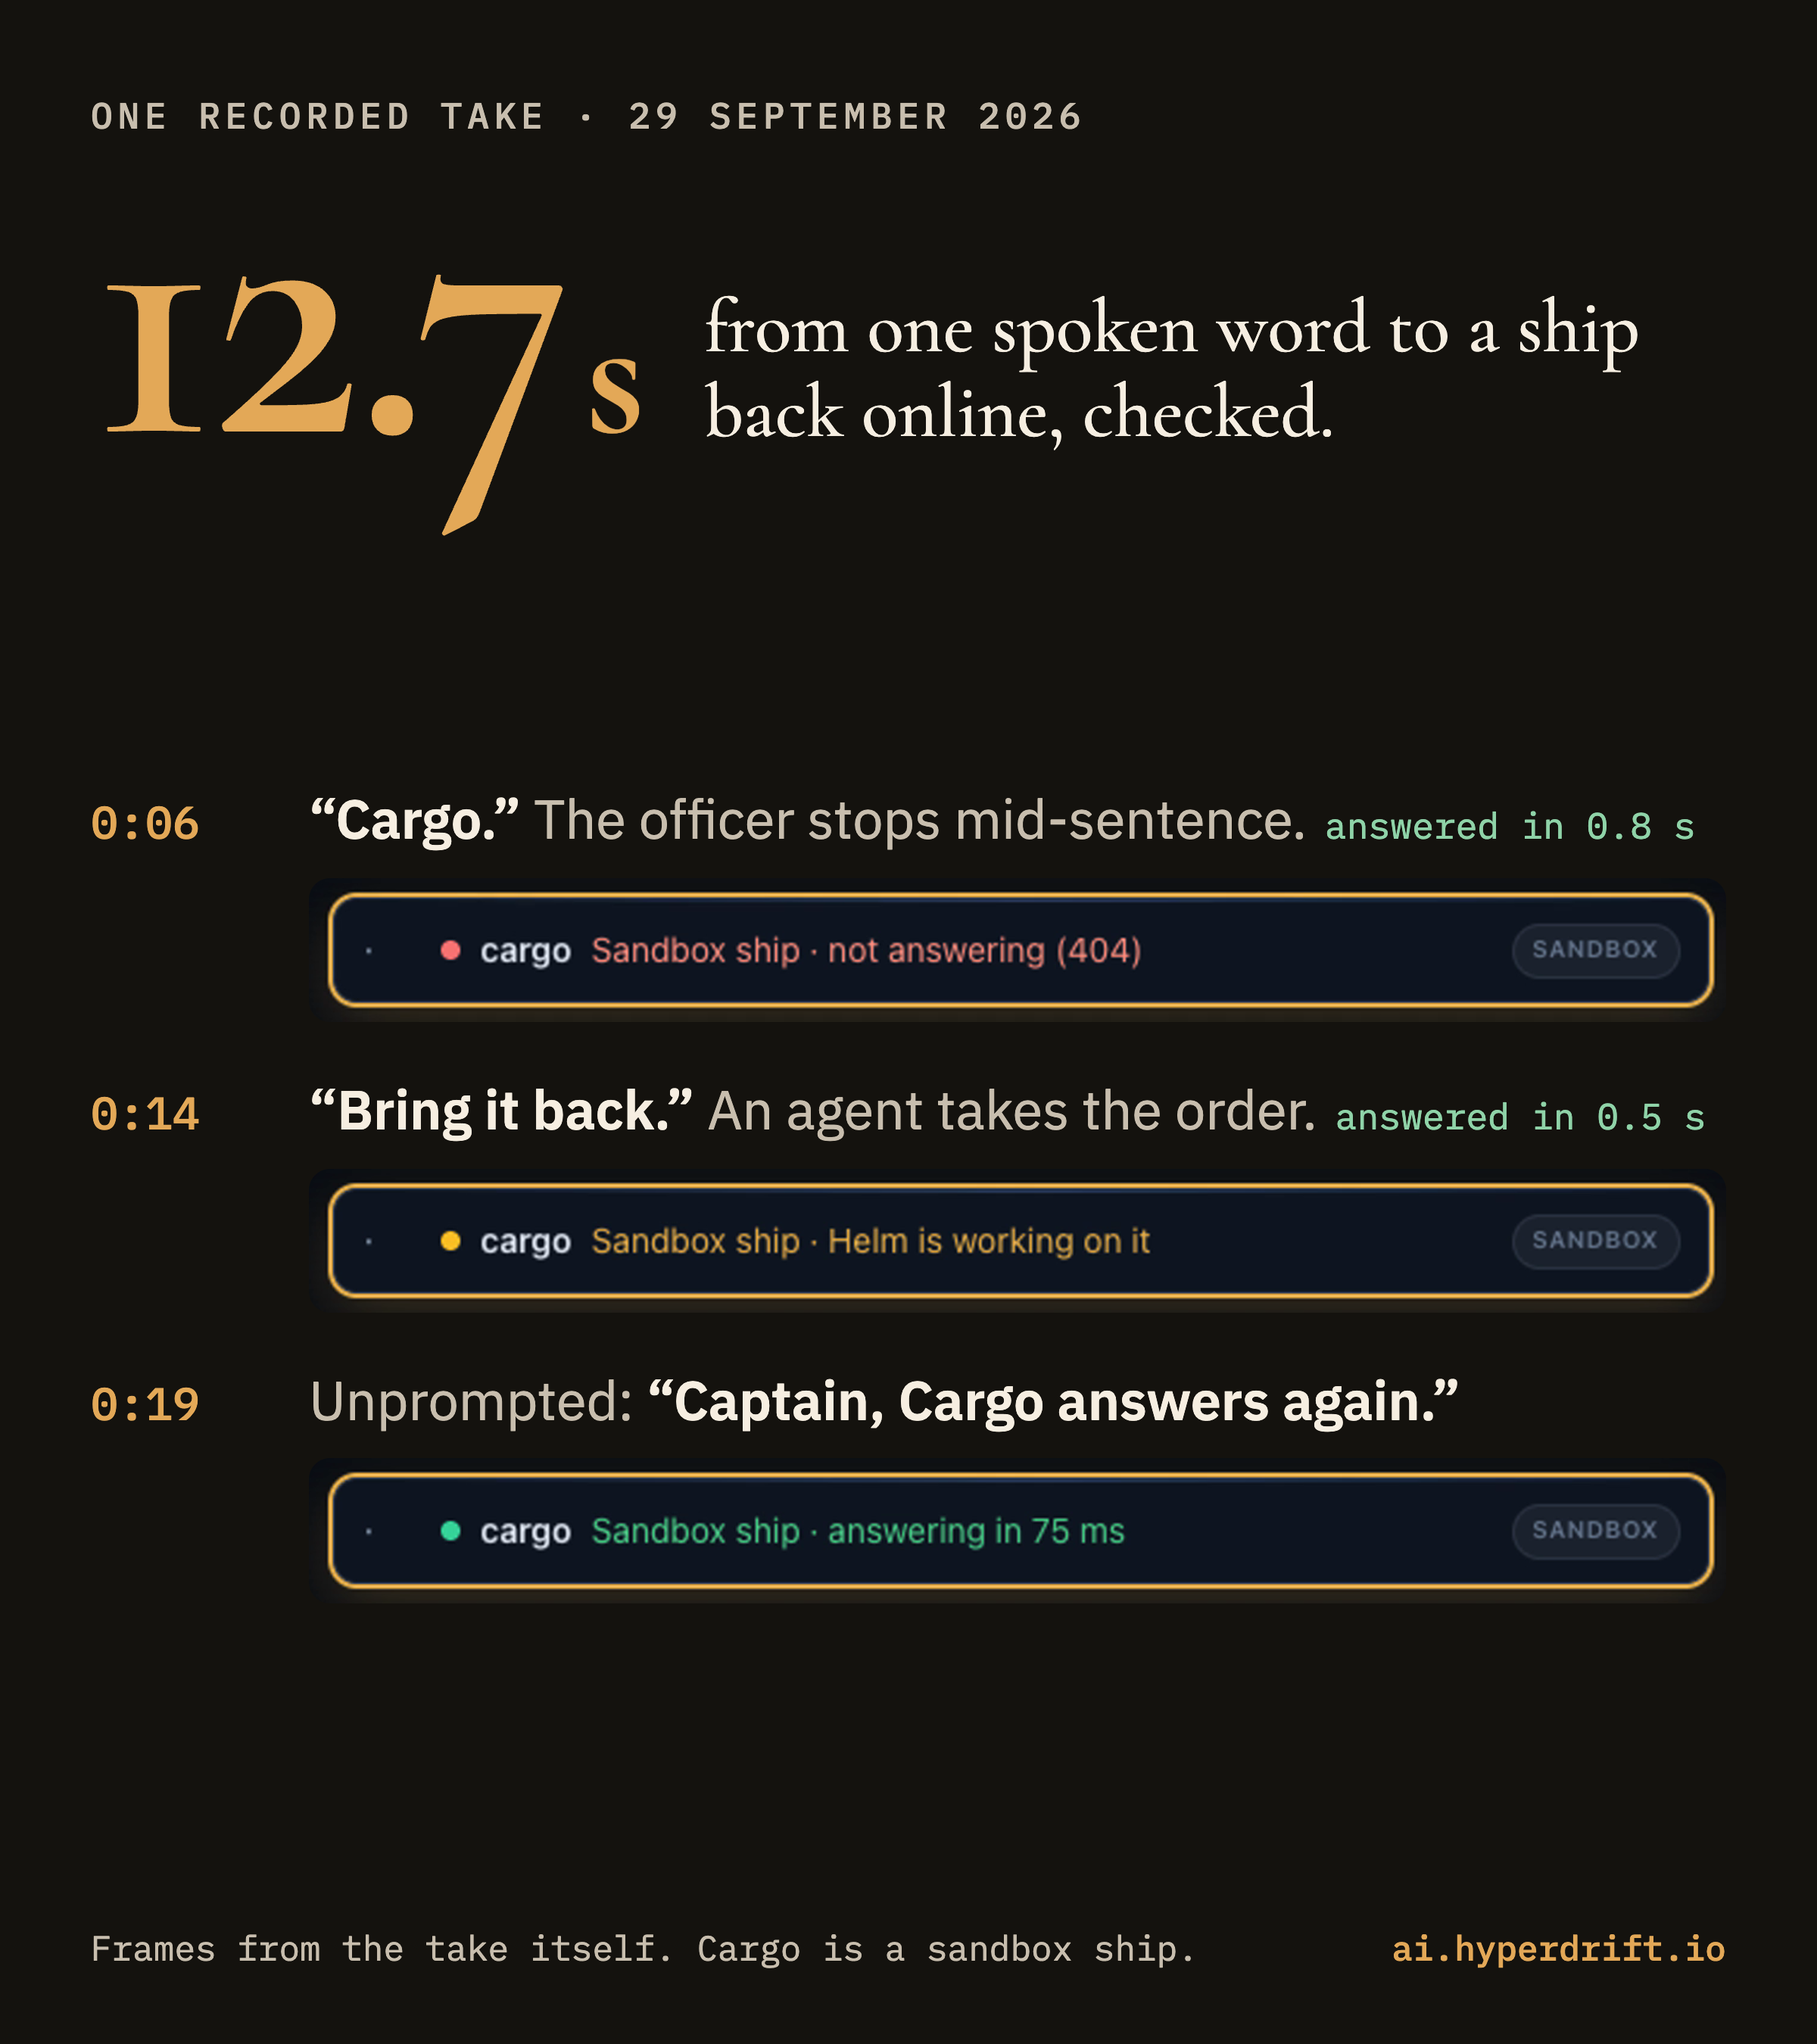
The officer is mid-sentence when you say one word: "Cargo". It stops, and tells you the ship is down. You say "bring it back". An agent restores it. The officer checks the ship twice from outside, then tells you, without being asked.
You never touch the screen. But the screen never stops following you: the ship you named comes forward, the rest step back, and every choice the officer offers appears as a button, for whoever is looking over your shoulder.
Response time in the recorded tests
Across four takes of six turns on 29 September, answers began 0.5–0.8 seconds after the generated captain’s voice ended. The longest conversational silence was 1.2 seconds. That measures response onset; the interval from the captain’s first word to the report was 12.7 seconds in the recorded take.
That pace took three decisions. The listening model hears you and calls the end of your turn on its own; the one we use was released the day we recorded, trained on real conversations with voice agents, where people say "yes", "why" and "Cargo" and expect to be understood. The officer is its own model: it decides every line before anyone asks a large model to think. And the voice is rented from the same platform, so the words are spoken the moment they are decided.
There was one wall. With the speech API we tested in September, a voice that had started a sentence could not be stopped. So when you talk over the officer, it does what a person does: it goes quiet, hangs up on itself, and picks up a fresh line while you are still speaking. You hear a pause of about a second. Underneath, a whole session ended and another began.
Rent the voice, own the judgement
AssemblyAI hears and speaks. That half is bought, and it should be; nobody should build their own ears.
We used AssemblyAI for speech recognition and speech output, and kept the operating decisions in our own code. The response path selects lines from the agenda and its evidence. Its accuracy still depends on those records and the checks behind them.
So build in that order. Write the decisions down first, with their evidence. The voice comes after, and it is the easy part.
Who it leaves out
A voice is not the door for everyone. If you cannot hear, or cannot speak, or work in a room where talking is not an option, the officer is only useful because everything it says is on the screen as well, and because you can type to it. That is not a footnote. An interface that only works for people who resemble its author has not shipped.
The next step is the same idea with less in the way: dictate straight to the tools your apps expose to agents, and let the screen be optional.